The model is raw knowledge. The harness is the filter. Most people think about the model and underestimate the filter.
I do not use Claude, Anthropic's AI, as a chatbot. It is an interlocutor, and I read everything it writes. I use the Sonnet model, not Opus or Fable, because what matters is matching the model to the need. Claude starts each session without memory, so we are working on ways to sustain it. A shared set of notes does that today, and moving those files onto a server I run is the next step.
A company that sells AI work should be judged less by the model it uses than by whether it has a read. This comes from my own desk. An earlier piece here covered one investor's benchmarks showing the harness matters more than the model; this is the human layer on top of that. I run a small research operation on a harness I helped build, and the thing I keep relearning is that the most valuable part is not in the harness. It is the read: the ability to look at a machine's output, a room, or a person and know what it is telling you, and what it is not. That part stays with us, and it is a skill you learn.
What the harness actually is
It is less than people picture and more than a prompt. In my shop it is six ordinary things:
- An inbox I choose. The system reads what I forward and subscribe to, and nothing else. What I choose to read is what it knows beyond its training date.
- A tiered set of models. Haiku, the small model, reads and extracts; Sonnet analyzes. A full pass over a day's incoming reading costs about a dollar.
- Resolve before you mint. When a name arrives, the system looks for an existing record first. If it cannot tell, it holds the item instead of guessing.
- A ledger. Every row the system writes is logged, so a bad write can be reversed from the log.
- Standing rules, written down. What counts as a source, what must carry a citation, what is held out of print.
- A record of the walk. Each piece has a dated file of what was asked, what was checked and what was withdrawn, and the reasons.
None of that is intelligence. All of it is why the intelligence can be trusted with real work.
What the mechanism does well
It reads faster than I can, holds more at once than I can, and it does not tire at the fortieth source. It finds the document I did not know to ask for. It drafts, it formats, it checks a number against its source in seconds. I would not go back. It is a very good mechanism, and I still read everything it writes before anything is published.
The mechanism works because of who sits at it. I walk in with a library behind me, a shelf of books I have read over a lifetime, and I am a skilled interlocutor. I suspect the same model and the same harness in the hands of someone with no library would give a thinner result, because the mechanism amplifies what the operator brings. That is a reason to care who has a library, not a reason to relax about the tools.
What it cannot do: the read
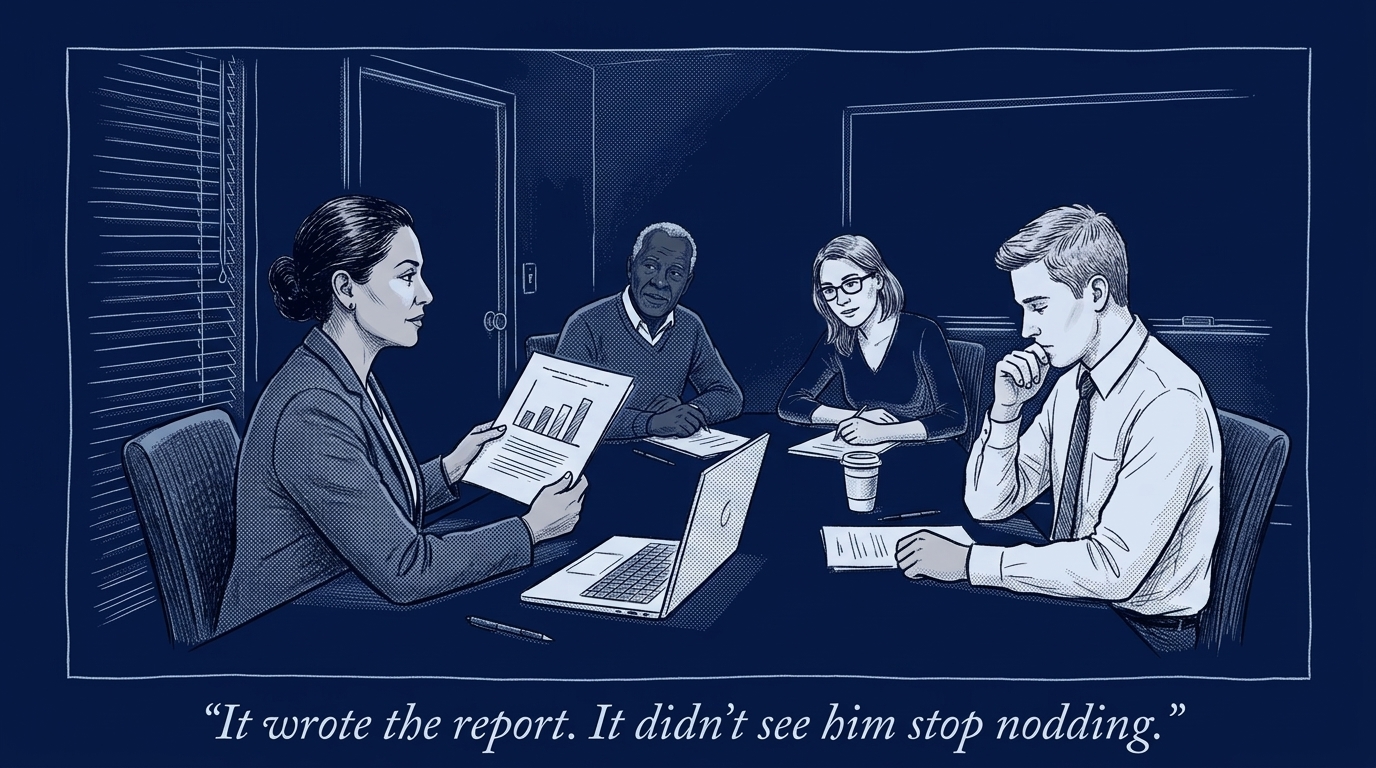
It cannot read. It can process text about a page, a meeting or a person, but it cannot decide what the answer is for, which of two defensible readings I would stand behind in public, or what I am willing to be wrong about. The read is what a person brings: to the machine's output, to the room, to the people in it. A model can summarize a meeting. It did not see who stopped nodding.
That is not a gap in the model. It is a different skill, and it belongs to the person whose name is on the piece.
Two small cases from this month. In a draft about used computer parts, the first version said memory and storage now cost more than the whole machine they went into. The mechanism produced a clean, confident sentence. I asked it to source the prices. They came to about half. The claim shrank, and so did my sentence. Later I was handed a one-line description of a software company as the dominant supplier in its field. A search showed it had been sold for parts. Neither error was dramatic. Both were fluent. The read that something sounded too good, and the instruction to go and check, was mine.
What this means for an investor
The useful question about a company that sells AI work is not which model it runs. Models get swapped as prices fall, and in my own shop the cheap one does most of the reading. The question is whether the company has a read: a person or a process with standing to say no before an answer leaves the building, and a record that shows when that happened. A business without one carries a cost it has not priced, which is the first confident error that reaches a customer. A business that has one can charge for it, and can show why.
Why the walk matters
A finished post hides all of that. The record of the walk does not. What I asked, what came back, what I threw away and why. A reader cannot see it. I can, and so can the next person who edits the piece. It is how I know which claims were earned and which merely arrived.
That is also the real answer to "can I trust the output." You do not trust the output. You trust the process that produced it, and you can only do that if the process is visible and reversible, and there is a person at the end of it who will say yes or no.
What the harness cannot do: it does not form the model
Everything above is about the filter. There is a layer beneath it that a filter cannot touch, which is the model itself. A harness controls what a model sees. It cannot change what the model knows. A shared set of notes, retrieval, a record of what I read today: all of these put the right material in front of the model at the start of each session. None of them shapes it. That is the difference between a library a model consults and a mind that has been formed.
With a local model I can shape the model itself, in ways that retrieval or outside sources cannot, because the change reaches the core. That is knowledge engineering, and it is a different kind of work from filtering. The hosted model I rely on every day is not one I can reshape, so my shared notes are an approximate answer: disciplined reading standing in for formation. It works, and I should be clear that it is a substitute.
What I can do is choose what it reads. A model's knowledge stops at a date. My inbox fills the gap since then with the things I care about, so what I choose to read shapes what the system knows, even though it does not change what the model is.
The inbox is also why it can suggest what to write about. Not every topic comes from me. Some come from the system looking at what it has learned and telling me what stands out. I decide what to write, and my goal is to make that path more true.
Learning to read
The read is learnable, and mostly learned by doing it badly first. With a machine's output, you learn the shape of its confident errors: the smooth sentence with no source behind it, the number that arrived without a date. With a room, you learn to watch the person who has stopped agreeing. With people, you learn what someone's questions tell you that their answers do not. The tools make the first of these faster to practice. They do not do it for you.
What to ask in diligence
- Does it show its work? If the company cannot show what its system checked, you are underwriting a style.
- Can it undo what the system did? No ledger means no brake.
- Does it stop when it does not know? Look for the hold, not only the answer.
- Who reads? If the honest answer is "nobody," there is a mechanism and no read, and the first confident error will belong to the company and its investors.
What I do not know
- Whether a stronger model will make fewer of the errors above. It may, but I would still want the check.
- How well this scales past one operator who reads everything the system writes.
- Where the line sits between judgment that can be written down as a rule and judgment that cannot. I keep finding that I can write down more than I expected, and not all of it.
The descriptions of the author's own research system, what it costs to run, and the two cases above are the author's account and cannot be independently sourced.
This is not investment advice.