A Venture Capitalist Spent Three Months Proving It With Benchmarks: the Harness Beats the Model. The Edge Was Never in the Weights — It's in the Room You Run Them In.
September 25, 2026 · 4 min read
Two weeks ago this section argued that the durable edge in AI has moved off the model and onto the system around it — the room the model runs in. That was an argument. Here is the evidence, and it has been arriving every few days from a venture capitalist who has spent three months documenting the same claim under a different word: the harness.
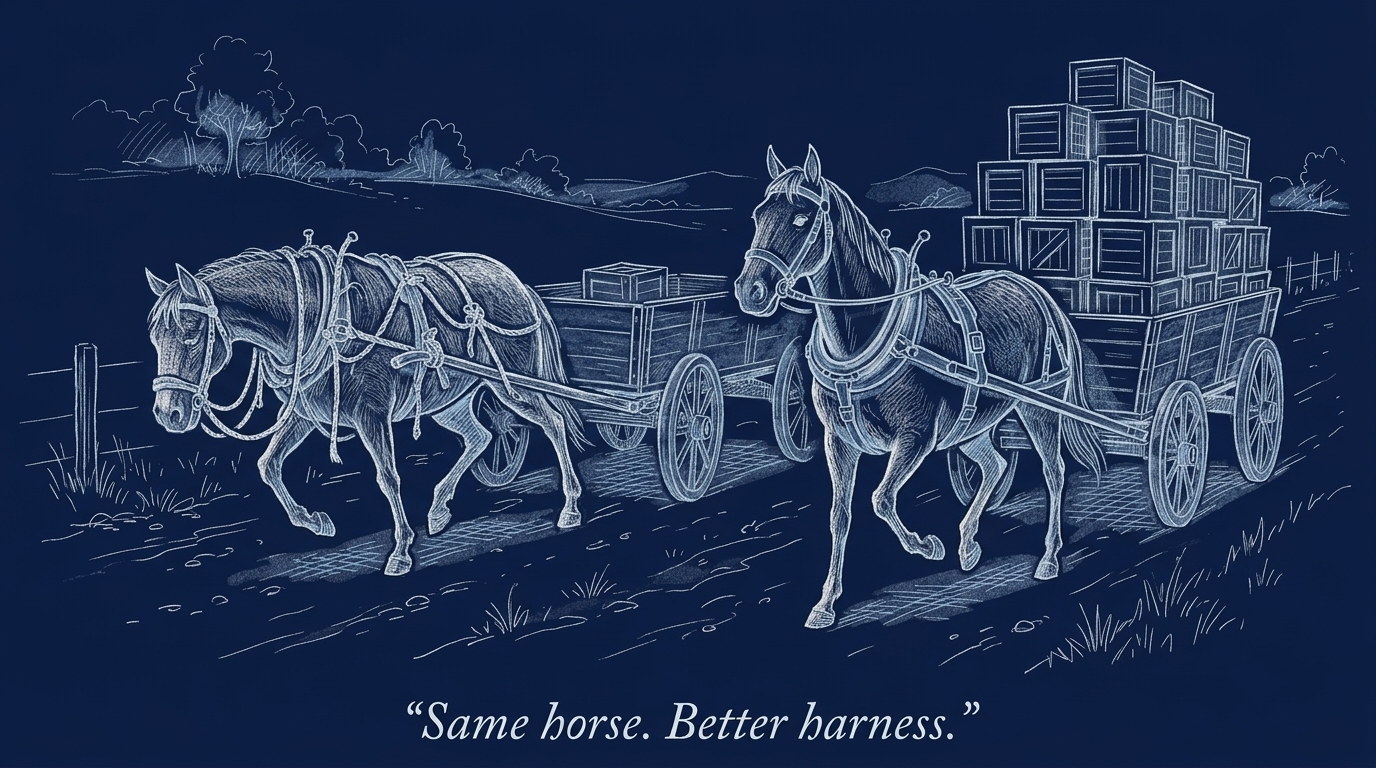
Tomasz Tunguz of Theory Ventures has written a steady run of posts making one point: the software layer that executes a model — the harness — has more effect on real-world performance than the model itself.[1] The claim comes with numbers, which is what separates it from a slogan. In testing he reports from Endor Labs, one model — GPT-5.5 — scored around 61.5% functional correctness inside one harness and differently inside others: the weights were constant, the result was not. A separate Berkeley result he cites shows a better-engineered harness cutting the cost of a task by roughly 71% with no loss of accuracy.[2] Hold the model fixed and change the room, and you change the product. That is not an opinion about AI; it is a benchmark.
The rest of this analysis is for Pro and Enterprise members.
You have read the opening. Members get the full piece, with the evidence and sources behind it.